Tested by AiIndex | Updated
For conversation, check what went missing
For the short announcement, Riverside was a convenient choice. The two-minute conversation was less reassuring: all three tools missed the line explaining what the team was designing. We'd use these as a first draft, not a finished record.
We ran a 25-second synthetic English recording, with and without noise, then a two-minute English conversation with four people from the AMI Meeting Corpus. These were AI-assisted browser tests using free tools; no paid plans or completed registrations. One conversation isn't enough to rank overall accuracy.
| What we tried | Two-minute conversation | Before using the transcript |
|---|---|---|
| Riverside (official site, opens in a new tab) Free upload, English About Riverside | Conversation:Left out the reply beginning "I just got the project announcement", including what the team was designing. | Before using it:TXT and SRT downloaded without promotional text. Neither file identified the speakers. Check for missing replies before using it as a record. |
| TurboScribe (official site, opens in a new tab) Free trial without an account, English | Conversation:Kept "I just got the project announcement", but missed "Designing a remote control" later in the reply. | Before using it:TXT included speaker labels and a promotional message. We accidentally left the speaker count at two, so this run cannot judge four-speaker separation. |
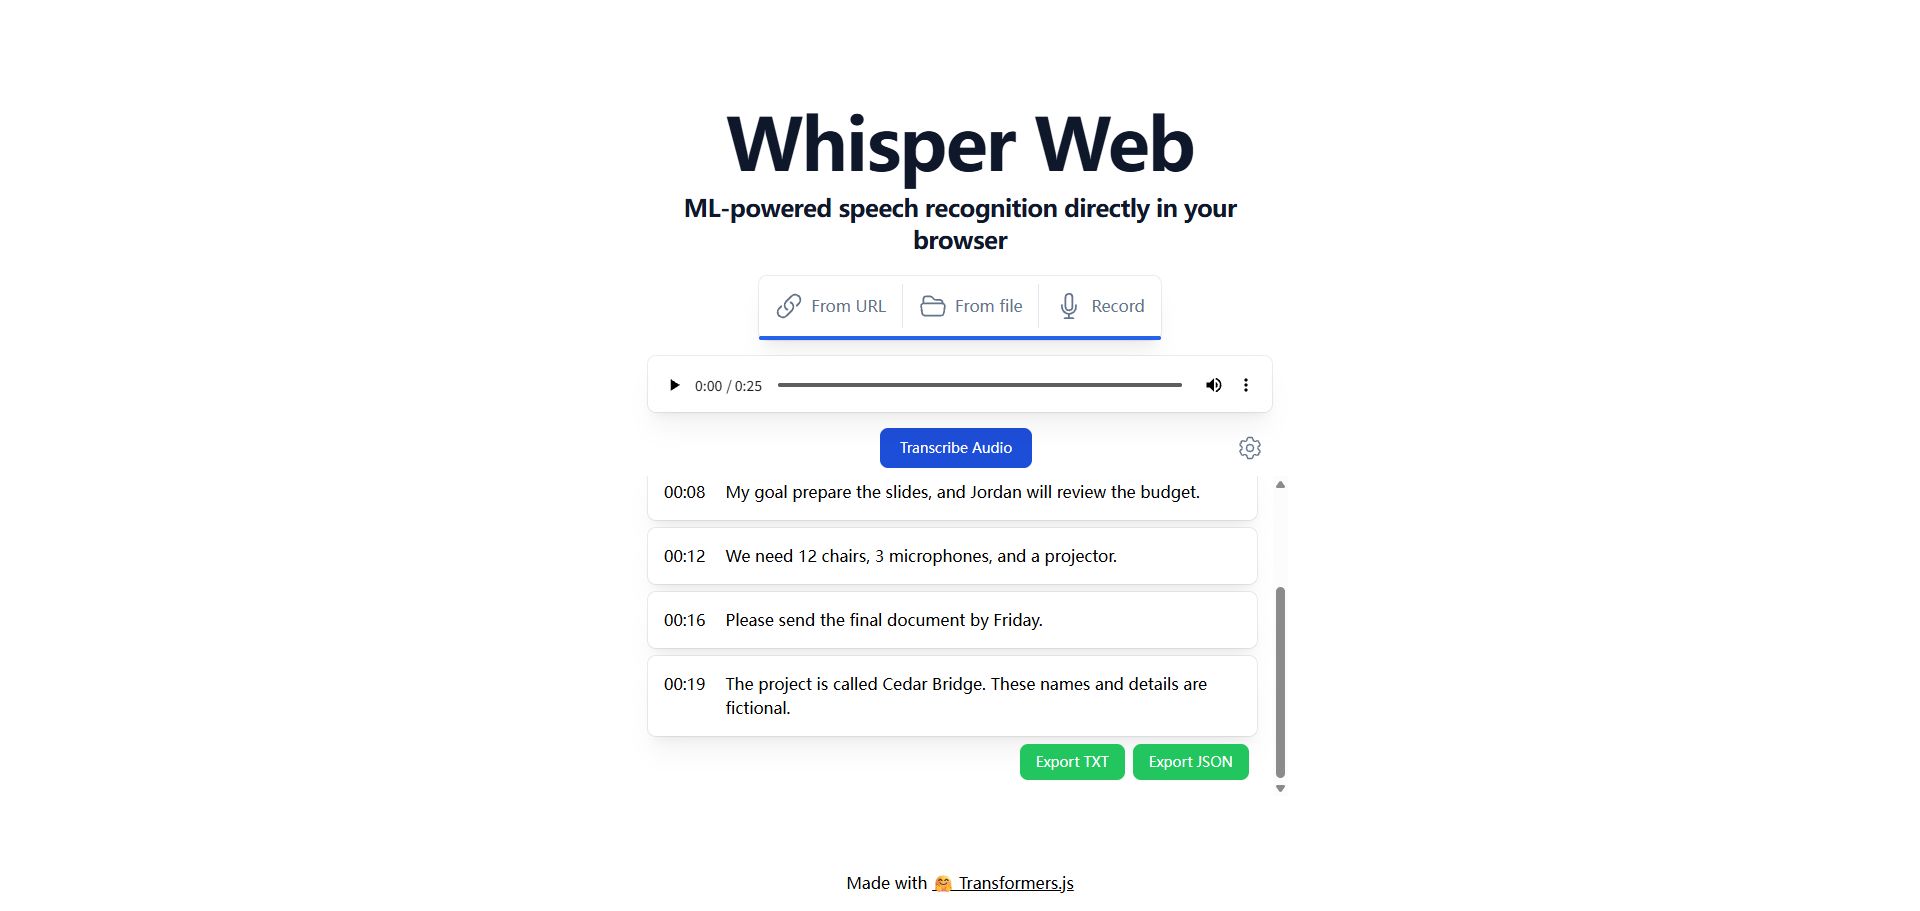
| Whisper Web (official site, opens in a new tab) Browser demo, small English model (tiny.en) | Conversation:Missed the same remote-control detail, changed "go first" to "go to the price", and repeated "Blue" at the end. | Before using it:The tiny.en model needed the most obvious cleanup in these examples. Its JSON had no speaker labels and no finish time for the last segment. Larger models were not tested. |
The earlier clear recording was easier: all three kept its wording. With added noise, Whisper Web changed "Maya will prepare" to "My goal prepare"; Riverside and TurboScribe kept the name. Those original files are still available below.
The sentence all three left out
Around 00:17, one person explains the task: "Designing a remote control." Other people give short acknowledgements during the reply. The official human transcript includes the detail, but none of our three downloads does. Without it, the exchange still reads smoothly. That's why checking grammar alone wouldn't catch this omission.
- AMI human transcript, speaker A, 00:16.68 to 00:18.20
- Designing a remote control.
- Riverside, TurboScribe and Whisper Web
- This sentence is missing from all three outputs.
Whisper Web also changed "go first" to "go to the price" and ended with a long run of "Blue". We tested its small tiny.en model, not the whole Whisper family. The full output is in the downloads; we haven't shortened or corrected it.
Subtitle downloads need their own check. Riverside's SRT had no promotional message; TurboScribe's did. TurboScribe also put one short sentence in a caption lasting about 18 seconds. We checked the files, not how the subtitles look or stay in sync over video.
Listen and check the original files
The recordings, transcripts and settings are here, including the mistakes.
Two-minute conversation: audio, human transcript and downloads
Four-person conversation, 2 minutes
WAV: Four-person conversation, 2 minutesThis is a recorded role-play design meeting, not an AiIndex customer call. The excerpt starts and ends mid-conversation. Read the human transcript with speakers and timings alongside the audio; overlapping replies are kept separate.
- Whisper Web
- JSON from Whisper Web, conversation
Audio and manual transcript: AMI Meeting Corpus, AMI Consortium / University of Edinburgh, under CC BY 4.0. ES2002a headset mix, cropped to source seconds 120-240; no denoising or speed changes. Transcript grouped by speaker and pauses for reading. No endorsement implied. Original license notice.
Earlier 25-second test: results, audio and downloads
On , we used a fictional announcement read by a synthetic voice. All three kept the clear recording's wording, allowing for punctuation and equivalent numbers such as "nine thirty" and "9.30".
- Riverside
Got the words right, including Maya's name. The text file had no promotional message, just an extra colon at the top. We didn't test the subtitle download.
- TurboScribe
Got the words right, including Maya's name. The free downloads included a TurboScribe message. In the subtitles, 9.30 was split between two captions.
- Whisper Web
Changed "Maya will prepare" to "My goal prepare". The download was a JSON file, mainly useful for coding. The last line was missing its finish time.
Clear recording
WAV: Clear recordingSame recording with noise
WAV: Same recording with noiseThis is a sample recording for a transcription comparison. The planning meeting is on Tuesday at nine thirty in the morning. Maya will prepare the slides, and Jordan will review the budget. We need twelve chairs, three microphones, and a projector. Please send the final document by Friday. The project is called Cedar Bridge. These names and details are fictional.
How we tested, and what this comparison cannot tell you
We used browser automation to submit the same files and inspect the results. No transcripts were edited before export. The first test used Microsoft Zira Desktop at 16 kHz mono, with a second version adding noise at approximately 15 dB SNR. These are variants of one synthetic recording, not two independent real-world examples.
The October 27 test used the same 120-second, 16 kHz mono WAV for all three tools. We compared selected passages against AMI's official manual annotations v1.6.2, not an independently re-annotated transcript. Four people have words in the reference, though their speaking time is uneven. We kept overlaps separate and did not calculate an accuracy percentage or score cut-off words at the excerpt boundaries.
Whisper Web used Xenova/whisper-tiny.en with quantization and multilingual mode off. Riverside used its public English uploader. TurboScribe used English and the default Whale mode without translation or audio restoration. Its speaker recognition was off in the short test and on in the conversation test.
We made a setup mistake in the conversation test: TurboScribe's speaker count stayed at its default of two. Its TXT therefore has two labels, which cannot establish whether it can separate all four people. The free quota was exhausted after that run, so we have not retested four speakers or automatic detection. That limit belongs to this test, not to the product.
We downloaded both TXT and SRT for Riverside's conversation result; the earlier short test only checked TXT. TurboScribe's conversation SRT used the direct download, with 17 captions and no speaker names. The earlier SRT used eight words, ten seconds and eighty characters per segment, with sentence-aware segmentation on. Our TurboScribe interface was in Chinese, which explains the promotional messages and speaker labels in its exports.
AMI is a known research corpus, so we don't know whether these systems encountered it during training. We haven't tested long meetings, other languages, live meeting bots, privacy promises or subtitle sync against video. Browser automation delays also make speed comparisons unreliable. Before uploading a confidential recording, check the provider's data-use terms.